Automation Exception Handling Checklist
Use an automation exception handling checklist to detect failed steps, preserve context, assign recovery, prevent duplicate actions, and verify completion.
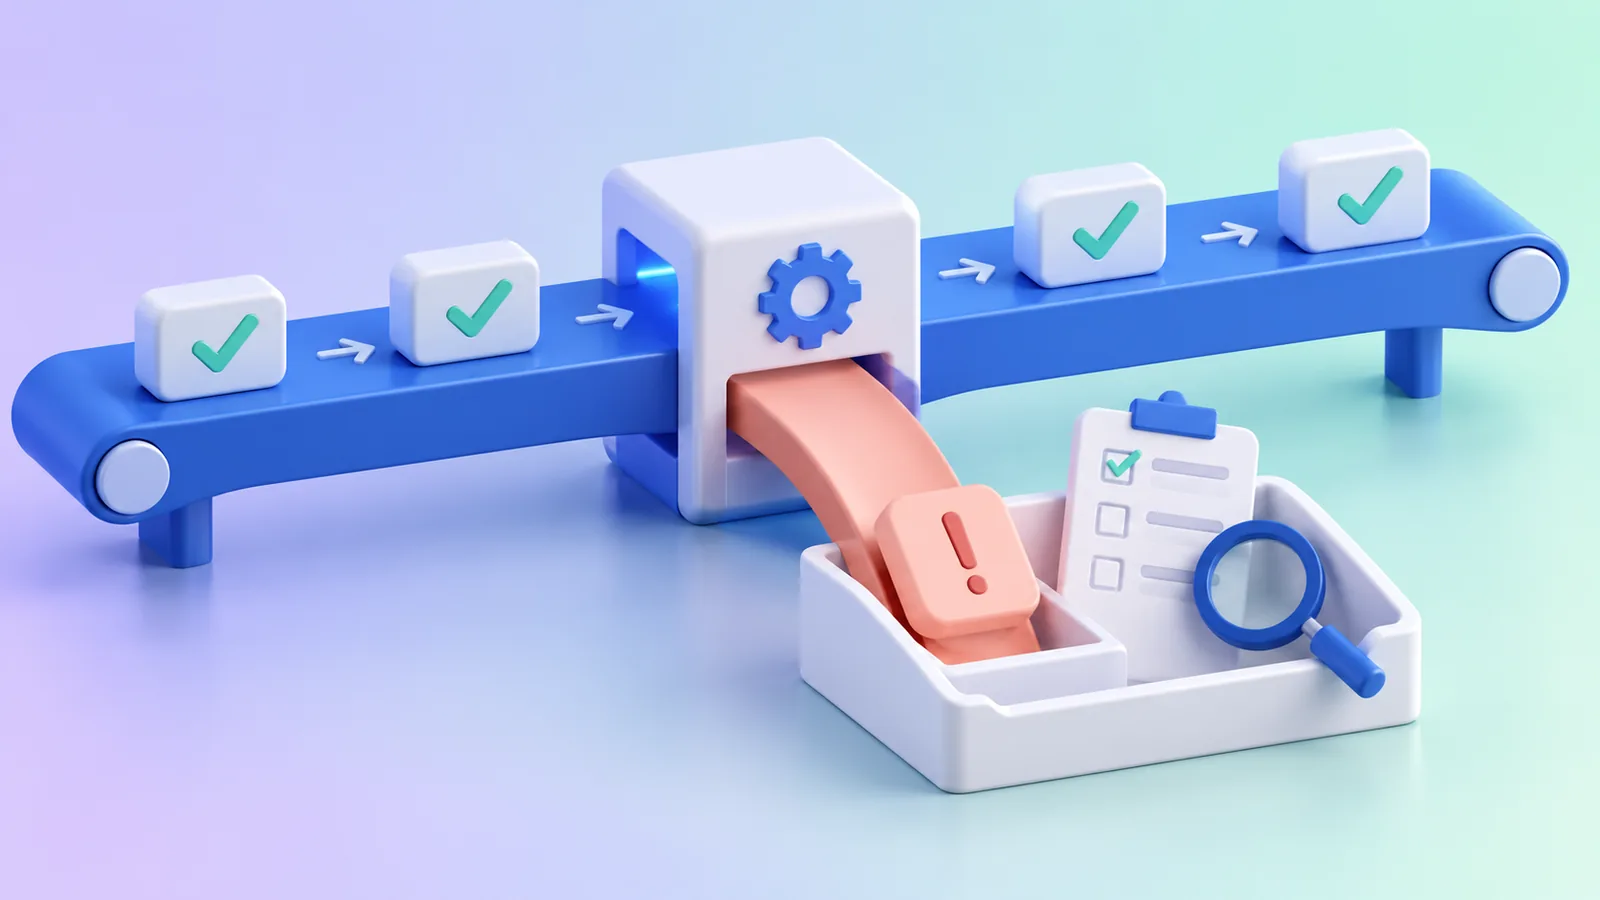
Automation exception handling makes unusual and failed cases visible. A workflow is incomplete if it only describes the successful path. The team needs to know how failures are detected, who responds, and how recovery avoids repeating an action that already succeeded.
Define failure and uncertainty
List missing inputs, invalid records, tool errors, permission changes, partial completion, and unexpected outcomes. Distinguish a confirmed failure from an unknown result. Retrying an uncertain external action without checking its state can create duplicates.
Build the exception record
| Field | Purpose |
|---|---|
| Case identifier | Locate the affected work |
| Failed or uncertain step | Understand where progress stopped |
| Completed actions | Avoid repeating successful work |
| Context | Preserve the inputs needed for review |
| Owner | Assign recovery responsibility |
| Resolution | Record the action and verification |
Keep records appropriate to the information involved. Do not expose unnecessary client or sensitive data in broad alerts.
Assign a monitored route
Choose where exceptions arrive and who covers that route. Define handling priorities according to business consequence. An error email sent to an abandoned inbox does not establish monitoring.
Design recovery deliberately
In an illustrative workflow, a lead record is created but the owner notification fails. Recovery should send or restore the missing notification after confirming the existing record. Replaying the entire workflow without checking can create a second lead and confuse ownership.
Ask the technical owner to implement appropriate safeguards for repeated triggers and uncertain outcomes. Verify the business result after recovery, not merely that the retry command returned successfully.
Test representative exceptions
Use controlled cases to exercise missing data, temporary downstream failure, repeated input, and partial completion. Confirm that the owner receives a usable alert and can recover the case. Keep consequential external actions within a controlled test arrangement.
Learn from recurring failures
Classify causes and review repeated exceptions. A growing manual queue can indicate unstable inputs, a changed integration, or a poorly chosen automation boundary. Repair the underlying process rather than treating every failure as an isolated incident.
Frequently asked questions
Should every error retry automatically?
No. Safe retry depends on the step, confirmed state, and duplicate-action controls. Some cases require new information or human review.
What counts as a resolved exception?
The intended business outcome is verified or an authorized alternative is recorded. An alert marked read is not a completed recovery.
Who owns the workflow long term?
Name both an operating owner and the technical support route. Tool ownership alone does not establish responsibility for affected client work.
Put this into practice
Map the failed and uncertain paths of one active automation. Test a partial-completion case and confirm that recovery restores the missing outcome without duplicating completed work.
For the wider operating context, start with Educo’s service business approach. To discuss the constraint in your own business, talk to Educo.